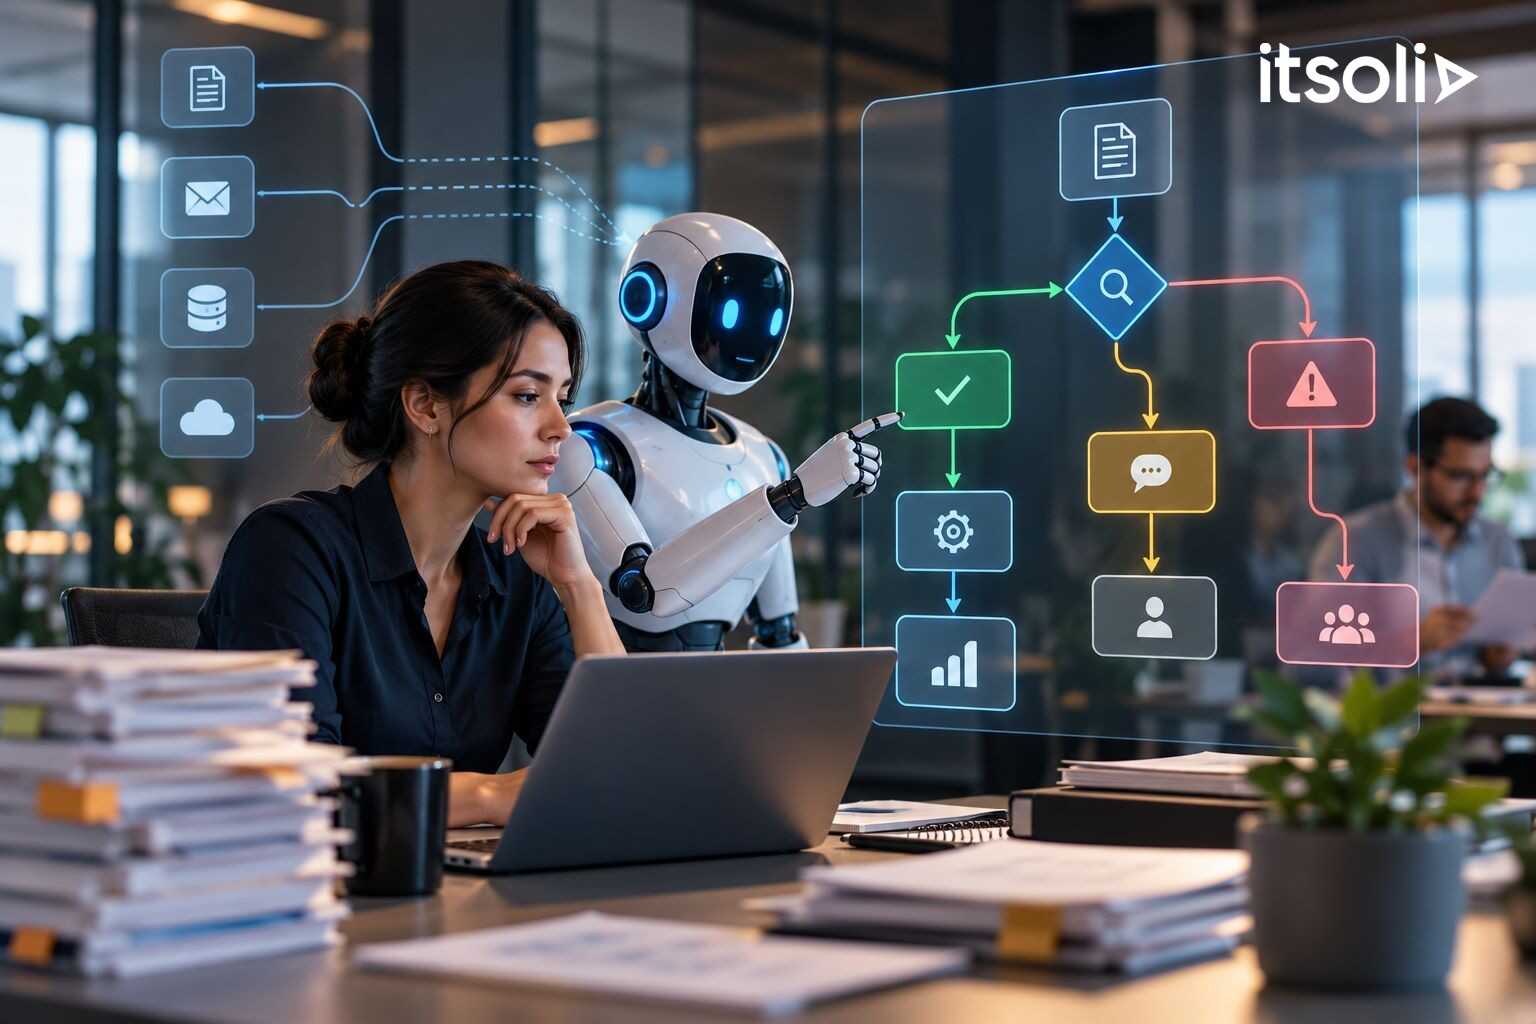
Designing AI Exception Handling Before Automation Goes Live
October 27, 2026
Enterprise automation demonstrations usually show clean input, a clear rule, and a successful output. Live operations are rarely that tidy. Customer requests arrive with missing information. Documents conflict. External APIs time out. A policy may not cover a particular situation. AI can handle ambiguity better than conventional scripts, but that capability does not remove the need for exception design. Instead, it creates a new question: when should the system continue, ask for more information, route to a specialist, or stop entirely? Teams that answer this before launch tend to build more dependable workflows.
Classify Exceptions by Consequence
Not all exceptions deserve the same treatment. A missing product category may justify a clarification question. An uncertain customer identity might require human verification. A suspected payment discrepancy should halt an automated transaction. A useful taxonomy separates incomplete inputs, contradictory evidence, unavailable systems, policy conflicts, low-confidence interpretations, and high-impact actions. Each category needs a defined response. The design should also recognise compound failures. An uncertain recommendation combined with an unavailable approval service is more serious than either issue alone. The goal is predictable behaviour when reality differs from the happy path.
Create an Explicit Decision Ladder
Exception handling works best as a sequence of increasingly conservative options. First, validate whether the input can be corrected automatically using trusted sources. Second, request clarification if the user can resolve the ambiguity. Third, send the case to an appropriate queue with a concise explanation and supporting evidence. Finally, suspend or reject actions whose risks exceed the permitted threshold. This ladder should live in workflow logic and policy services rather than only in a model instruction. The model may recognise an issue, but a reliable system needs deterministic rules for escalation and execution.
Make Human Intervention Useful
Human review often fails because reviewers receive a vague warning and must reconstruct the entire case. An effective handoff includes the original request, information already checked, the proposed action, a clear reason for escalation, and the specific decision required. Review interfaces should allow correction of source data as well as approval or rejection. Feedback should be captured in a structured form that improves routing rules and evaluation sets. People should not be reduced to clicking approval buttons for every uncertain case. Their attention should concentrate on decisions that benefit from context, accountability, or judgment.
Prevent Loops and Duplicate Actions
Retries are essential for resilience, yet poorly implemented retries can create duplicate orders, repeated notifications, or conflicting record updates. Every action with external effects needs an idempotency strategy, a transaction identifier, and a clear state model. Workflows should distinguish a request that failed before execution from one whose response was lost after a successful action. Time limits, retry ceilings, and compensation steps should be documented. For example, an agent should check whether a booking was created before attempting the same booking again. These controls turn exception handling from a support procedure into a reliability discipline.
Learn from Exception Patterns
An exception queue is a rich source of operational intelligence. Track exception volume by workflow stage, root cause, resolution time, business impact, and percentage successfully recovered without manual intervention. Repeated failures may reveal missing data ownership, unclear policies, or poor integration design rather than a weak model. Review the highest-volume and highest-impact categories separately. Fixing the common issue improves efficiency; fixing the rare severe issue protects the business. Enterprises that treat exceptions as design inputs can expand automation with measured confidence instead of accumulating invisible operational risk.
An Operational Readiness Checklist
Before launch, take ten representative failures and walk through the response with operations, product, engineering, and risk teams. Confirm who receives each case, what context they see, and how the workflow resumes. Test missing approvals, stale records, and lost network acknowledgements rather than assuming they are rare. Agree which cases must be blocked regardless of performance targets. Document the decisions as executable workflow rules where possible. Revisit the checklist after major integration or policy changes so the exception playbook stays aligned with the live system.
Exception management should distinguish defects from legitimate uncertainty. A model asking for clarification because a user supplied two different invoice numbers is behaving responsibly, while an agent inventing a number to complete the task is not. Product teams should reward safe abstention in evaluation criteria rather than counting every incomplete workflow as a failure. It is equally important to measure unnecessary escalations, since routing routine cases to humans can erase the expected gains of automation. Balancing those outcomes requires regular calibration with business specialists. The exception process should also inform service commitments.
Support teams need to know whether an escalated case remains within the original response target and whether the customer should receive an interim update. Cases should retain their history when moving between automation and people. Without that continuity, employees repeat investigations and customers experience a fragmented process. An effective design recognises that the handoff is part of the service, not an embarrassing interruption to it.
For implementation teams, the most important next step is to choose one measurable workflow, document its decision points, and establish clear ownership of both technical and business outcomes. Review actual user cases at a regular cadence, including successful outcomes and difficult exceptions. Translate findings into changes to source data, policy, interface design, and test coverage rather than relying on prompt adjustments alone. This operating rhythm keeps improvement tied to evidence and prevents a promising prototype from becoming an unmanaged dependency.
What Leaders Should Take Forward
Operational resilience is designed before the first exception appears. Clear escalation paths, safe retries, and high-quality human handoffs allow AI workflows to handle the difficult cases that inevitably surface when a pilot becomes a business service.
Service alignment: AI Adoption & Transformation | Custom AI Models & Agents

© 2026 ITSoli

